Rule 30 and the Surprise of Complexity
The previous chapter gave us a simulator that can run any of the 256 elementary rules. Now we pick one and look at it closely. Rule 30 is the standard demonstration of why cellular automata are worth studying.
Its transition table contains eight bits — the same encoding as in the previous chapter, repeated here so you can check the simulator line by line:
111 110 101 100 011 010 001 000
 0   0   0   1   1   1   1   0
Start from one active cell and repeatedly apply that rule.
The result rapidly stops looking like something generated by a tiny deterministic program.
The left side develops visible diagonal structure.
The rest of the pattern, and especially the center column, looks irregular, with no obvious repeating motif.
The important lesson is not that Rule 30 is “random.”
It is completely deterministic.
The lesson is that determinism does not imply simple-looking behavior.
Generate Rule 30
Using the simulator from the previous chapter:
history = run(rule_number=30, width=241, generations=120)

import matplotlib.pyplot as plt

plt.figure(figsize=(12, 8))
plt.imshow(history, cmap="binary", interpolation="nearest")
plt.title("Rule 30")
plt.xlabel("cell")
plt.ylabel("generation")
plt.show()
The canonical book figure is generated with:
python scripts/figures/cellular-automata/part01_foundations.py 03
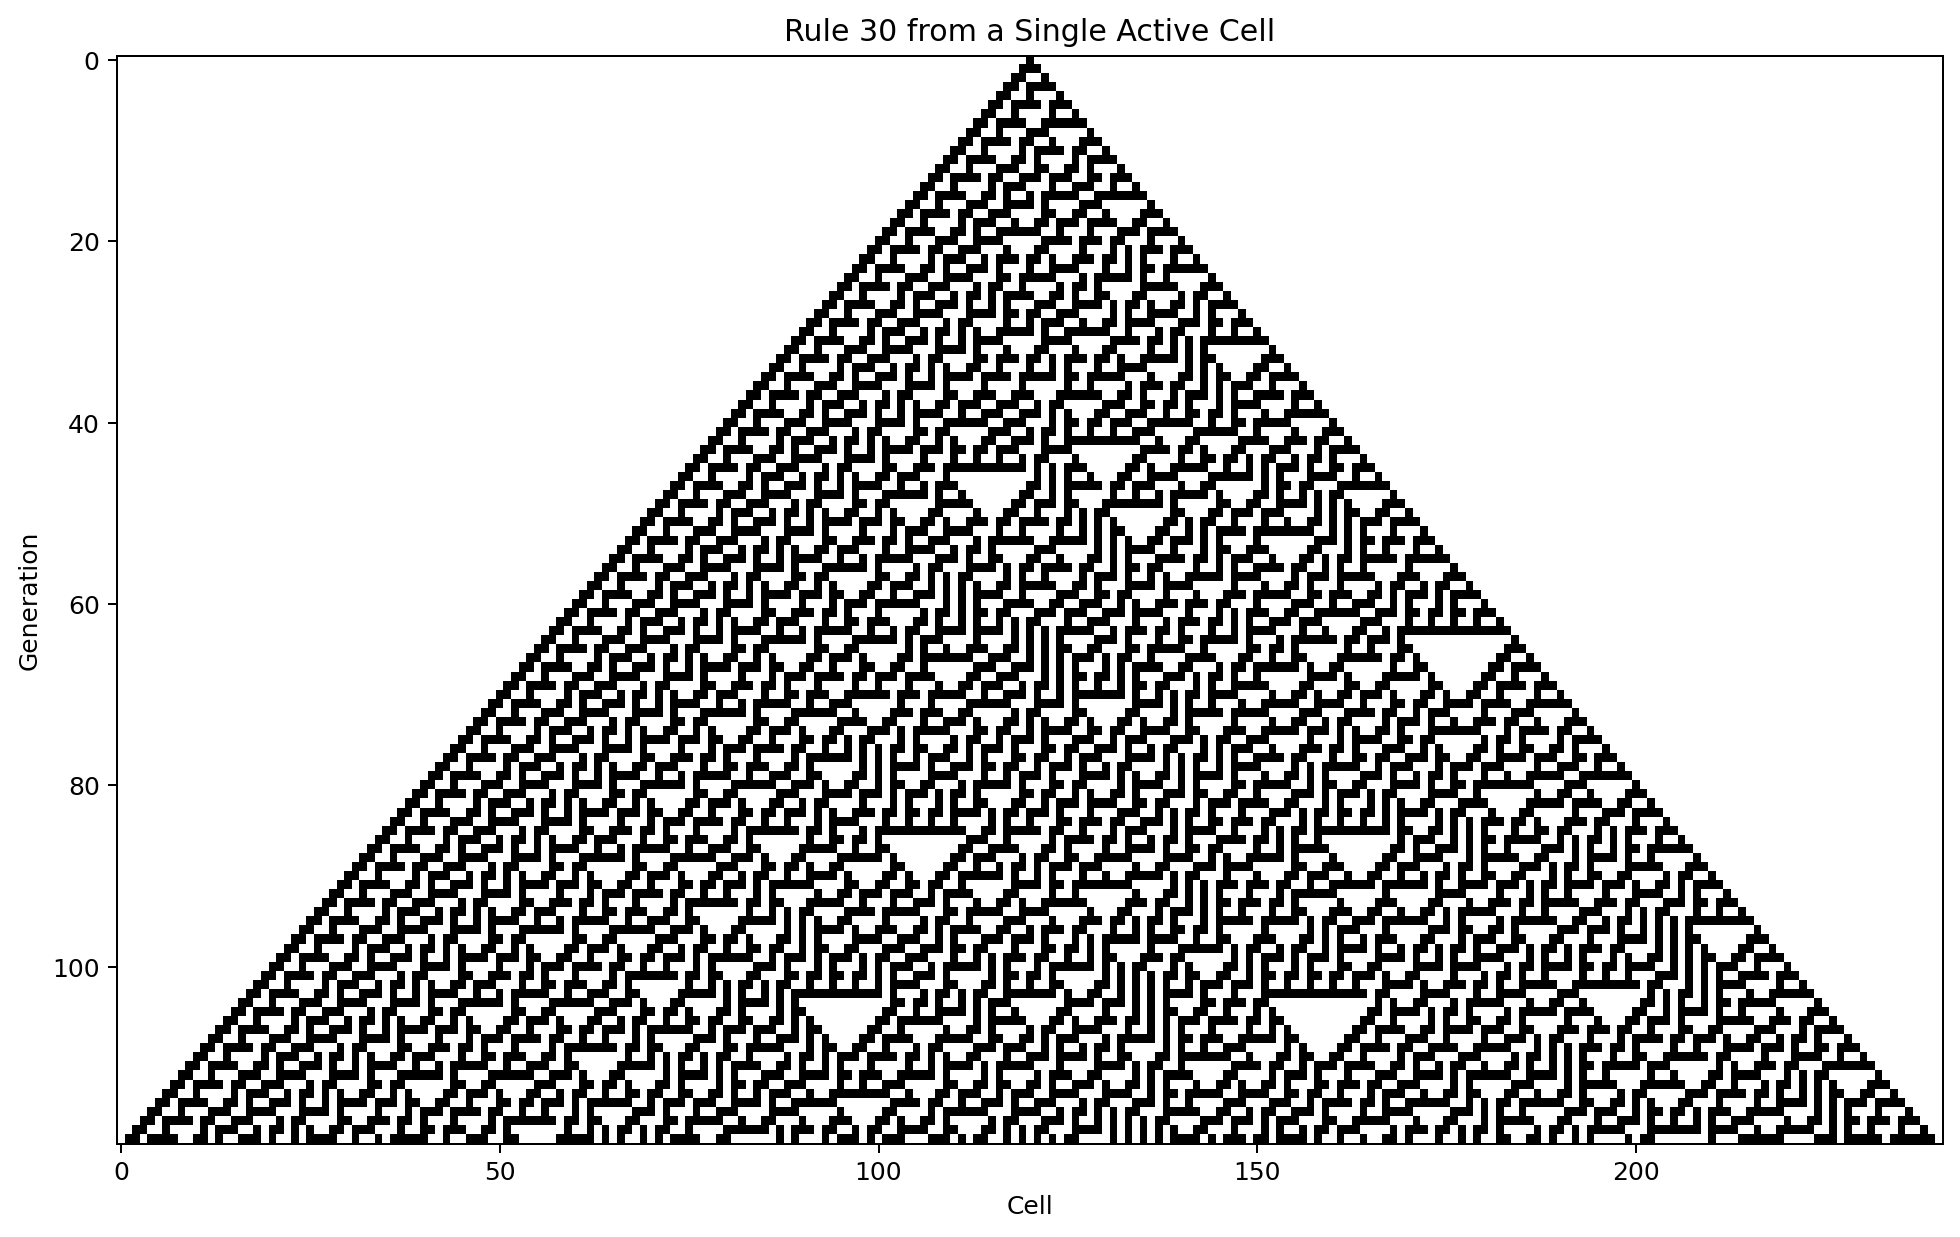
The initial state contains almost no information:
one active cell
The rule contains only one byte of choices.
Yet the history becomes visually rich.
Follow one column through time
A useful experiment is to treat one cell position as a sensor.
centre_column = history[:, history.shape[1] // 2]
print("".join(map(str, centre_column)))
The first bits read 1101110011... — the beginning of a recorded sequence (OEIS A051023) that remains non-repeating for at least the first billion steps observed to date.
We can inspect any vertical slice:
for offset in (-20, -10, 0, 10, 20):
    column = history[:, history.shape[1] // 2 + offset]
    print(offset, "".join(map(str, column)))
This changes our perspective.
The image view asks:
What spatial structure does the automaton produce?
The column view asks:
What signal does a fixed location experience through time?
The same automaton can therefore be studied as both pattern generator and signal generator.
That second view is historically significant: Wolfram proposed the center column as a pseudorandom number generator, and it was used for large integers in the Wolfram Language. It passes many standard statistical tests. But passing tests is an empirical observation, not a proof of randomness — a distinction the final sections of this chapter make precise.
Sensitivity to initial conditions
Let’s compare two worlds that differ by one cell.
width = 241

a = np.zeros(width, dtype=np.uint8)
a[width // 2] = 1

b = a.copy()
b[width // 2 + 7] = 1
Run both. The previous chapter’s run hardcodes a single-cell start, so we generalize it to accept any initial state:
def run_from_state(initial_state, rule_number, generations):
    state = initial_state.copy()
    history = [state.copy()]

    for _ in range(generations - 1):
        state = step(state, rule_number)
        history.append(state.copy())

    return np.array(history)

ha = run_from_state(a, 30, 100)
hb = run_from_state(b, 30, 100)
Now measure their disagreement:
difference = ha != hb
fraction_different = difference.mean(axis=1)
Plot it:
plt.plot(fraction_different)
plt.xlabel("generation")
plt.ylabel("fraction of different cells")
plt.show()
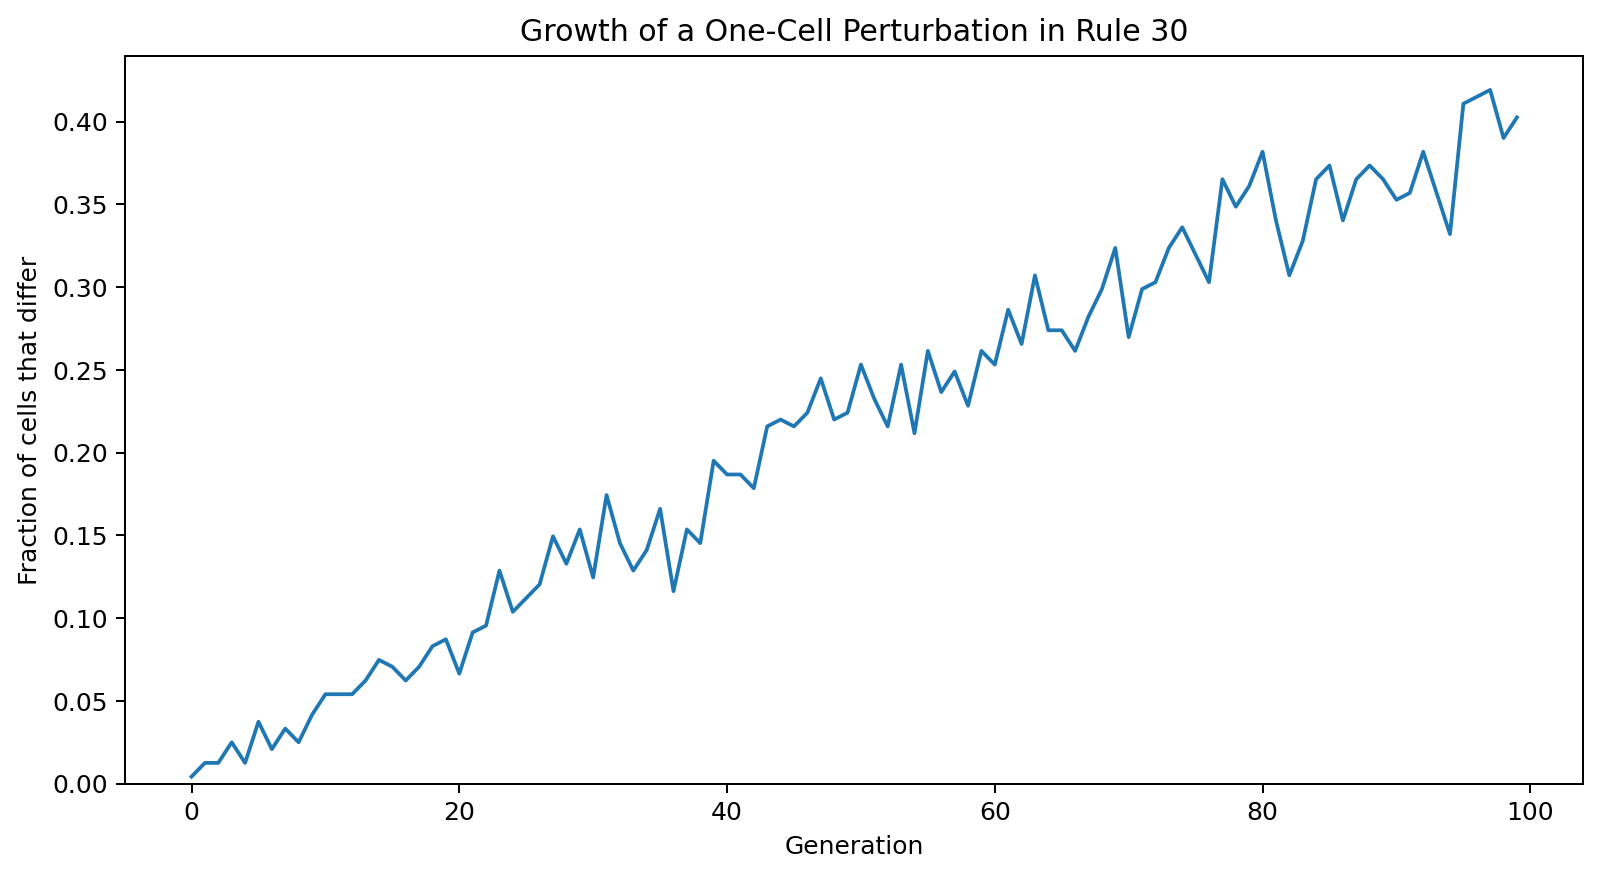
A one-cell change spreads from a few cells per thousand to more than a quarter of the row within a hundred generations — but only through the causal cone permitted by the local neighborhood.
That phrase matters: local causality constrains the speed of influence.
With radius-one neighborhoods, information cannot jump arbitrarily far in one update.
Chapter 22 will formalize sensitivity as its own observable. Here it is a first observation: small causes, bounded speed, large eventual divergence.
Draw the causal cone
Suppose a perturbation starts at position i at time t = 0.
After one step, only these cells can have been affected:
i-1 i i+1
After two steps:
i-2 ... i+2
After t steps, no effect can exist outside:
[i - t, i + t]
    flowchart TD
    A[One changed cell at t = 0] --> B[At most 3 affected positions at t = 1]
    B --> C[At most 5 affected positions at t = 2]
    C --> D[Influence remains inside a radius-t causal cone]
So even when the resulting pattern looks irregular, it is still governed by strict local propagation.
This is a useful theme in distributed systems too: locality constrains causality even when the aggregate behavior becomes difficult to predict.
Complexity is not the same as randomness
We can compare Rule 30 with genuinely independent random bits.
rng = np.random.default_rng(7)
random_history = rng.integers(
    0, 2, size=history.shape, dtype=np.uint8
)
Both may look irregular.
But Rule 30 contains spatial and temporal dependencies because every cell is produced from a specific local predecessor state.
A good exploration therefore asks more than whether two images “look random.”
We can compare:
- cell density,
- run lengths,
- neighborhood frequencies,
- autocorrelation,
- compressibility,
- perturbation growth.
For example, crude compression gives us a quick diagnostic:
import zlib


def compression_ratio(history):
    raw = np.packbits(history.astype(np.uint8)).tobytes()
    compressed = zlib.compress(raw)
    return len(compressed) / len(raw)
(Chapter 20 will own this helper; the form shown here, bit-packed before compressing, is the preview. Measured on the Rule 30 run above: ≈0.47 against ≈1.00 for independent random bits of the same shape. Both numbers move with grid size and duration, which is part of the caveat, not an accident in it.)
This is not a formal complexity measure. It depends on the compressor, representation and sample size — a compressed length is an upper bound on description length, never a proof of randomness, and poor compression by one algorithm proves nothing about algorithmic randomness. But held constant across runs, it is still a useful diagnostic for telling structured histories apart from less structured ones.
What is established, what is observed, and what is still open
Rule 30 is where books in this area most often overstate the case, so this chapter keeps an explicit ledger:
ESTABLISHED
  The rule is fully deterministic; the table above defines it completely.
  Influence spreads at most one cell per step per side (causal cone).
  No two adjacent columns from a single-cell start both become periodic
  (Jen 1990): a proof about pairs of columns, not about one column alone.
  The rule has served as a practical pseudorandom generator
  (Wolfram Language large integers).

EMPIRICALLY OBSERVED
  The center column looks irregular and passes many standard
  statistical tests; it is non-repeating over at least a billion steps.
  Row densities, run lengths, and one-to-zero ratios drift toward
  balanced values as runs lengthen.

INTERPRETATION
  Wolfram's claim that such systems are "chaotic" or
  "computationally irreducible": a theoretical position about why
  shortcuts fail, not a theorem about every observable of Rule 30.
  Coarse observables can be predictable even when microscopic
  detail is not.

SPECULATION / OPEN
  Whether the center column ever becomes periodic.
  Whether zeros and ones occur equally often in the limit.
  Whether the nth center bit can be computed with substantially
  less than O(n) effort.
  These are the subjects of Wolfram's Rule 30 Prize Problems —
  open after decades, which is itself evidence for how little
  "looks random" settles.
The practical upshot: use Rule 30 where irregular deterministic output is wanted, but irregular-looking output alone never establishes cryptographic security, and no statistical battery turns an observation into a theorem.
A vectorized Rule 30 step
The loop implementation is ideal for learning.
NumPy lets us express the same neighborhood operation over the whole row:
def step_vectorized(state, rule_number):
    left = np.roll(state, 1)
    centre = state
    right = np.roll(state, -1)

    index = (left << 2) | (centre << 1) | right
    return ((rule_number >> index) & 1).astype(np.uint8)
Now:
state = step_vectorized(state, 30)
The conceptual model has not changed.
We merely moved the cell loop into array operations. (Verified: identical output to the loop version on the same inputs.)
This gives us a recurring performance principle for the book:
First make the local rule obvious. Then make the execution fast.
What Rule 30 teaches us
Rule 30 gives us several important ideas in one small system:
simple deterministic law
        +
minimal initial state
        |
        v
rich global history
It also teaches us to separate three claims:
hard to predict
!= random
!= nondeterministic
A deterministic local system can be difficult to summarize globally.
That gap between local simplicity and global behavior is the territory cellular automata let us explore.
In the next chapter we will look at a different kind of surprise: an elementary cellular automaton that can be arranged to perform universal computation: Rule 110.
Research
Weisstein, E. W. — Rule 30 (MathWorld). The factual spine of this chapter: binary encoding
30 = 00011110, center-column sequence (OEIS A051023), use as the Wolfram Language large-integer generator, left-side diagonal regularity, and Jen (1990) aperiodicity for pairs of adjacent columns. Check any Rule 30 claim here first. https://mathworld.wolfram.com/Rule30.htmlWolfram, S. — Announcing the Rule 30 Prizes (2019). The guardrail against overstatement: three precise open problems — eventual periodicity, limiting one-to-zero ratio, sub-O(n) shortcut — with the evidence to date (non-repeating over a billion steps, drifting ratios, failed shortcuts). Establishes that formal randomness for Rule 30 is unproven, not merely unmentioned. https://writings.stephenwolfram.com/2019/10/announcing-the-rule-30-prizes/
Wolfram, S. — Statistical Mechanics of Cellular Automata (Reviews of Modern Physics 55, 1983). The paper that introduced Rule 30 to systematic study alongside the full elementary survey. Useful for seeing which properties were observed from the start and which interpretations accumulated later. https://doi.org/10.1103/RevModPhys.55.601
Zenil, H. & Martinez, G. J. — Cellular Automata (Scholarpedia). Supplies the two qualifications this chapter leans on: deterministic irregularity must not be confused with an external source of randomness, and irregular-looking output alone never establishes cryptographic security. Also frames computational irreducibility as a claim about specific observables and resources, not a blanket theorem. http://www.scholarpedia.org/article/Cellular_automata